Hard for AI
Package the complexity
Advanced charts, spatial layouts, and coordinated interactions become tested components with a small set of meaningful parameters.
A few parameters → advanced, stable outputLearn how OWL Compose helps AI turn content into documents, and how we check the results.
Approach comparison
Direct generation is fast, but the result depends on the model. Templates are steadier, but limit what can be made. OWL Compose gives the agent room to compose while keeping the finished work stable, editable, and publishable.
You get a result quickly, but each run still depends on how well the model performs.
Easy to start and more predictable, but content and layout stay inside the template’s limits.
Compose layouts, charts, and visuals freely, then keep editing and publishing the same work.
Direct generation leads on speed and freedom; templates lead on predictability; OWL Compose is stronger across the whole workflow.
Published work
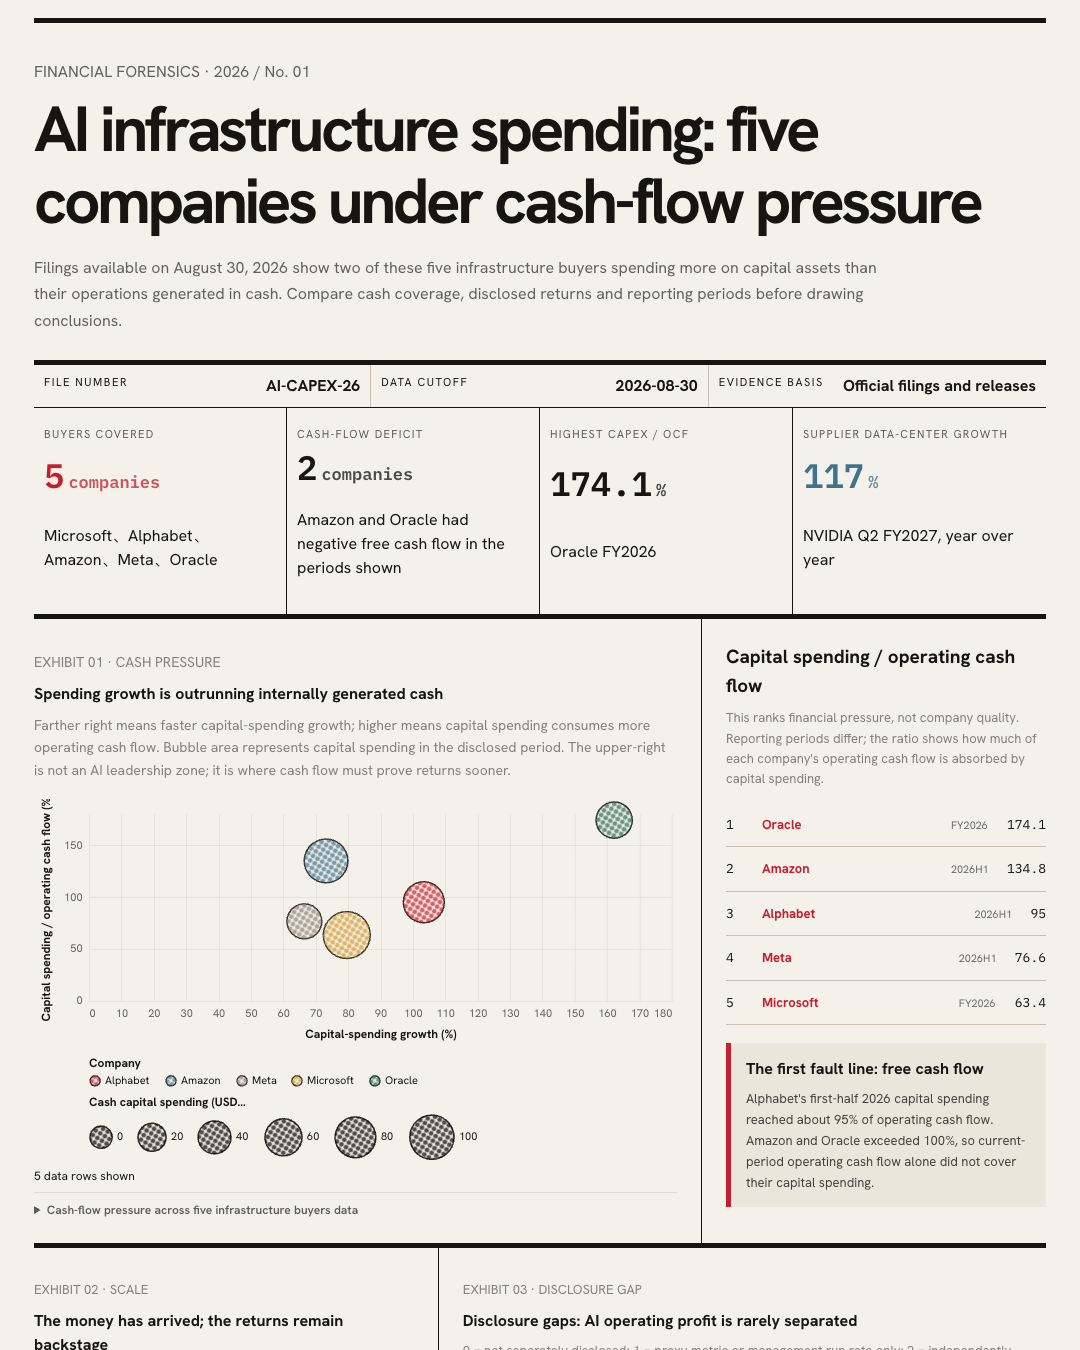
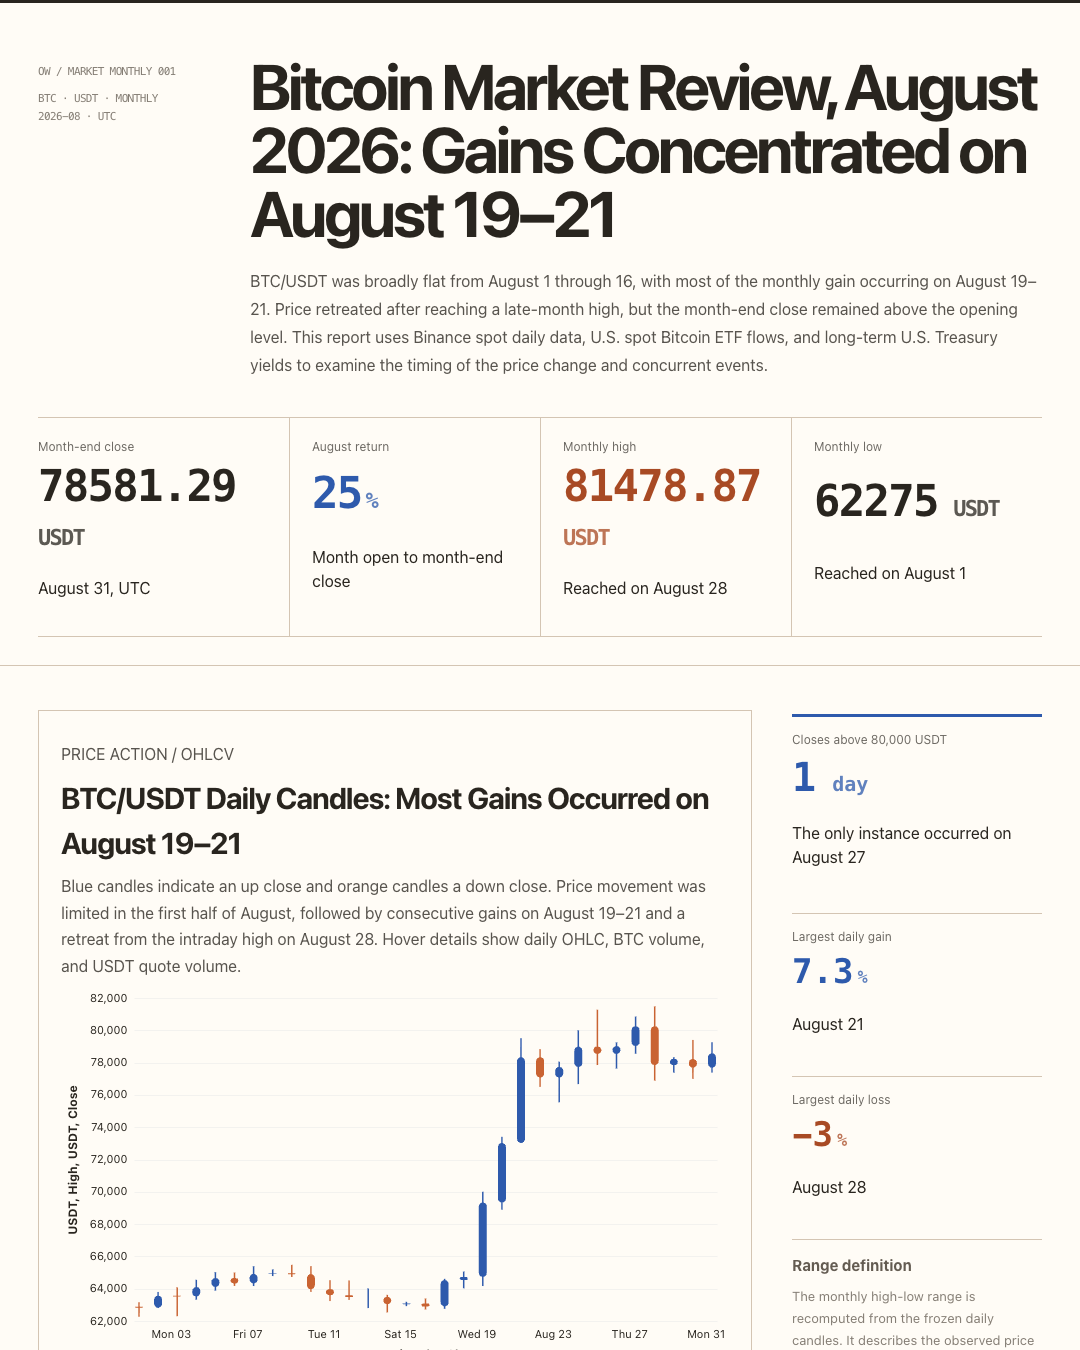
Open a published example to explore its content and charts.
Continuous testing
We repeatedly test OWL Compose on baseline models near the price–performance frontier. The tasks and configuration stay fixed; when models improve, we rerun the tests and adjust the system so that capability reaches the finished work.
Adaptive abstraction
The right authoring layer is not uniformly high-level or low-level. We set the boundary according to what baseline models can reliably create.
Advanced charts, spatial layouts, and coordinated interactions become tested components with a small set of meaningful parameters.
A few parameters → advanced, stable outputWhen models can compose reliably, we split the capability into finer primitives instead of locking it inside a template.
Fine-grained syntax → more creative freedomUsing the same baseline models and fixed tasks, we regularly ablate each layer. A boundary stays only when the evidence shows it helps.
15 model configurations · AA Index v4.2 · USD per index task
Colored points trace the upper envelope on a log-cost axis. Grey points cost more for the same or lower score; hollow points sit below the envelope. This is a sourced sample, not the full leaderboard. A frontier point is a candidate for our own work-quality tests, not proof of passing them. Missing task costs are excluded.
| Model | USD | AA v4.2 | Price–performance frontier |
|---|---|---|---|
| GPT-5.6 Luna (max) | 0.10 | 43 | Baseline candidate |
| GLM-5.3-Flash | 0.18 | 46 | Baseline candidate |
| DeepSeek V4 Flash 0731 (max) | 0.14 | 41 | Dominated |
| MiniMax-M3 | 0.23 | 36 | Dominated |
| DeepSeek V4 Pro 0813 (max) | 0.33 | 42 | Dominated |
| Gemini 3.1 Pro Preview | 0.34 | 37 | Dominated |
| Gemini 3.7 Flash (high) | 0.55 | 45 | Dominated |
| GPT-5.6 Terra (max) | 0.81 | 47 | Below the envelope |
| Muse Spark 1.3 (max) | 0.96 | 53 | Baseline candidate |
| GPT-5.6 Sol (max) | 1.25 | 51 | Dominated |
| GLM-5.3 (max) | 1.26 | 49 | Dominated |
| Kimi K3 (max) | 1.58 | 50 | Dominated |
| GPT-6 Astra (max) | 2.57 | 55 | Below the envelope |
| Claude Opus 5 (max) | 4.21 | 54 | Dominated |
| Claude Fable 5.1 (max, fallback) | 6.12 | 57 | Baseline candidate |